Publications
2026
Mapping Frictions in Interdisciplinary Privacy Research: Evidence from Eye-Tracking Researchers
Susanne Hindennach, Mayar Elfares, Céline Gressel, Andreas Bulling
Human Centered Security Meets Social Sciences - Mapping the Frictions (SOUPS), 2026.
AbstractBibTeXProject
Friction between human-centred security researchers and social scientists is widely felt in interdisciplinary work, yet rarely documented empirically. Drawing on a study with eye-tracking researchers about privacy and ethics in sensitive data use, we present four points of friction extracted from both participant responses and our own research process: differences in terminology, assumptions, and values, as well as the hidden labour underlying interdisciplinary collaboration. We argue that these frictions are not merely obstacles but productive sites of reflection - and that addressing them requires making implicit assumptions explicit, disclosing disciplinary boundaries, and consciously harnessing the tensions they create.
@inproceedings{hindennach26_soups,
title = {{Mapping Frictions in Interdisciplinary Privacy Research}: {Evidence from Eye-Tracking Researchers}},
author = {Hindennach, Susanne and Elfares, Mayar and Gressel, Céline and Bulling, Andreas},
year = {2026},
booktitle = {Human Centered Security Meets Social Sciences - Mapping the Frictions (SOUPS)},
}
REFLECTing SPERET: Measuring and Promoting Ethics and Privacy Reflexivity in Eye-Tracking Research
Susanne Hindennach, Mayar Elfares, Céline Gressel, Andreas Bulling
Proc. International Conference on Science of Cyber Security (SciSec), 2026.
AbstractBibTeXProject
Reflexivity - critical awareness of methodological choices, assumptions, and positionality - is essential for robust research, particularly when data are context-dependent and interpretive. It helps address bias, privacy, fairness, and societal impact. We focus on these human aspects in eye tracking (ET), and on the researchers who design, interpret, and deploy these systems. We choose ET as a leading example, given the very important impact of researchers: ET data acquires meaning only through experimental design, theoretical assumptions, and analytic pipelines. Small methodological decisions can significantly shape conclusions. As ET integrates with AI and real-world applications, the researcher's role becomes even more consequential. Yet privacy-preserving techniques remain limited, despite eye-tracking data revealing sensitive information such as identity, health, or cognitive states. Adopting such techniques requires researchers' critical reflection on privacy and ethics, but reflexive practices are rarely formalised in ET. We introduce two complementary tools developed with over 60 researchers: REFLECT, a qualitative questionnaire, and SPERET, a validated psychometric scale. REFLECT enables in-depth questioning of privacy and ethics in small teams, while SPERET enables community-level comparisons. Using REFLECT, we reveal recurring assumptions about generalisability and competing values in handling sensitive data that explain limited adoption of privacy techniques. SPERET operationalises these findings and consistently measures reflexivity. Together, our tools provide empirical insights into ethical reasoning and concrete instruments to promote more privacy- and ethics-conscious research practice at individual and community levels.
@inproceedings{hindennach26_scisec,
title = {{{REFLECTing SPERET}}: {{Measuring}} and {{Promoting Ethics}} and {{Privacy Reflexivity}} in {{Eye-Tracking Research}}},
author = {Hindennach, Susanne and Elfares, Mayar and Gressel, C{\'e}line and Bulling, Andreas},
year = {2026},
booktitle = {Proc. International Conference on Science of Cyber Security (SciSec)},
shorttitle = {{REFLECTing SPERET}},
}
QualitEye: Public and Privacy-preserving Gaze Data Quality Verification
Mayar Elfares, Pascal Reisert, Ralf Küsters, Andreas Bulling
Proc. ACM on Human-Computer Interaction (PACM HCI), 2026.
AbstractLinksBibTeXProject
Gaze-based applications are increasingly advancing with the availability of large datasets but ensuring data quality presents a substantial challenge when collecting data at scale. It further requires different parties to collaborate, therefore, privacy concerns arise. We propose QualitEye - the first method for verifying image-based gaze data quality. QualitEye employs a new semantic representation of eye images that contains the information required for verification while excluding irrelevant information for better domain adaptation. QualitEye covers a public setting where parties can freely exchange data and a privacy-preserving setting where parties cannot reveal their raw data nor derive gaze features/labels of others with adapted private set intersection protocols. We evaluate QualitEye on the MPIIFaceGaze and GazeCapture datasets and achieve a high verification performance (with a small overhead in runtime for privacy-preserving versions). Hence, QualitEye paves the way for new gaze analysis methods at the intersection of machine learning, human-computer interaction, and cryptography.
@inproceedings{elfares26_etra,
title = {{QualitEye}: {Public} and {Privacy}-preserving {Gaze} {Data} {Quality} {Verification}},
author = {Elfares, Mayar and Reisert, Pascal and Küsters, Ralf and Bulling, Andreas},
year = {2026},
booktitle = {Proc. ACM on Human-Computer Interaction (PACM HCI)},
number = {ETRA},
shorttitle = {{QualitEye}},
}
Ontology-Guided Diffusion for Zero-Shot Visual Sim2Real Transfer
Mohamed Youssef, Mayar Elfares, Anna-Maria Meer, Matteo Bortoletto, Andreas Bulling
arXiv:2603.18719, 2026.
AbstractLinksBibTeXProject
Bridging the simulation-to-reality (sim2real) gap remains challenging as labelled real-world data is scarce. Existing diffusion-based approaches rely on unstructured prompts or statistical alignment, which do not capture the structured factors that make images look real. We introduce Ontology- Guided Diffusion (OGD), a neuro-symbolic zero-shot sim2real image translation framework that represents realism as structured knowledge. OGD decomposes realism into an ontology of interpretable traits – such as lighting and material properties – and encodes their relationships in a knowledge graph. From a synthetic image, OGD infers trait activations and uses a graph neural network to produce a global embedding. In parallel, a symbolic planner uses the ontology traits to compute a consistent sequence of visual edits needed to narrow the realism gap. The graph embedding conditions a pretrained instruction-guided diffusion model via cross-attention, while the planned edits are converted into a structured instruction prompt. Across benchmarks, our graph-based embeddings better distinguish real from synthetic imagery than baselines, and OGD outperforms state-of-the-art diffusion methods in sim2real image translations. Overall, OGD shows that explicitly encoding realism structure enables interpretable, data-efficient, and generalisable zero-shot sim2real transfer.
@techreport{youssef26_arxiv,
title = {Ontology-{{Guided Diffusion}} for {{Zero-Shot Visual Sim2Real Transfer}}},
author = {Youssef, Mohamed and Elfares, Mayar and Meer, Anna-Maria and Bortoletto, Matteo and Bulling, Andreas},
year = {2026},
doi = {10.48550/arXiv.2603.18719},
}
Gaze3P: Gaze-Based Prediction of User-Perceived Privacy
Mayar Elfares, Pascal Reisert, Ralf Küsters, Andreas Bulling
Proc. Privacy Enhancing Technologies Symposium (PETS), 2026.
AbstractLinksBibTeXProject ACM Artifact Availabe
Privacy is a highly subjective concept and perceived variably by different individuals. Previous research on quantifying user-perceived privacy has primarily relied on questionnaires. Furthermore, applying user-perceived privacy to optimise the parameters of privacy-preserving techniques (PPT) remains insufficiently explored. To address these limitations, we introduce Gaze3P - the first dataset specifically designed to facilitate systematic investigations into user-perceived privacy. Our dataset comprises gaze data from 100 participants and 1,000 stimuli, encompassing a range of private and safe attributes. With Gaze3P we train a machine learning model to implicitly and dynamically predict perceived privacy from human eye gaze. Through comprehensive experiments, we show that the resulting models achieve high accuracy. Finally, we illustrate how predicted privacy can be used to optimise the parameters of differentially private mechanisms, thereby enhancing their alignment with user expectations.
@inproceedings{elfares26_pets,
title = {{{Gaze3P}}: {{Gaze-Based Prediction}} of {{User-Perceived Privacy}}},
author = {Elfares, Mayar and Reisert, Pascal and K{\"u}sters, Ralf and Bulling, Andreas},
year = {2026},
booktitle = {Proc. Privacy Enhancing Technologies Symposium (PETS)},
shorttitle = {{{Gaze3P}}},
}
2025
CryptoQA: A Large-scale Question-answering Dataset for AI-assisted Cryptography
Mayar Elfares, Pascal Reisert, Tilman Dietz, Manpa Barman, Ahmed Zaki, Ralf Küsters, Andreas Bulling
arXiv:2512.02625, 2025.
AbstractLinksBibTeXProject
Large language models (LLMs) excel at many general-purpose natural language processing tasks. However, their ability to perform deep reasoning and mathematical analysis, particularly for complex tasks as required in cryptography, remains poorly understood, largely due to the lack of suitable data for evaluation and training. To address this gap, we present CryptoQA, the first large-scale question-answering (QA) dataset specifically designed for cryptography. CryptoQA contains over two million QA pairs drawn from curated academic sources, along with contextual metadata that can be used to test the cryptographic capabilities of LLMs and to train new LLMs on cryptographic tasks. We benchmark 15 state-of-the-art LLMs on CryptoQA, evaluating their factual accuracy, mathematical reasoning, consistency, referencing, backward reasoning, and robustness to adversarial samples. In addition to quantitative metrics, we provide expert reviews that qualitatively assess model outputs and establish a gold-standard baseline. Our results reveal significant performance deficits of LLMs, particularly on tasks that require formal reasoning and precise mathematical knowledge. This shows the urgent need for LLM assistants tailored to cryptography research and development. We demonstrate that, by using CryptoQA, LLMs can be fine-tuned to exhibit better performance on cryptographic tasks.
@techreport{elfares25_arxiv3,
title = {{{CryptoQA}}: {{A Large-scale Question-answering Dataset}} for {{AI-assisted Cryptography}}},
author = {Elfares, Mayar and Reisert, Pascal and Dietz, Tilman and Barman, Manpa and Zaki, Ahmed and K{\"u}sters, Ralf and Bulling, Andreas},
year = {2025},
doi = {10.48550/arXiv.2512.02625},
publisher = {arXiv},
shorttitle = {{{CryptoQA}}},
}

QualitEye: Public and Privacy-preserving Gaze Data Quality Verification
Mayar Elfares, Pascal Reisert, Ralf Küsters, Andreas Bulling
arXiv.2506.05908, 2025.
AbstractLinksBibTeXProject
Gaze-based applications are increasingly advancing with the availability of large datasets but ensuring data quality presents a substantial challenge when collecting data at scale. It further requires different parties to collaborate, therefore, privacy concerns arise. We propose QualitEye–the first method for verifying image-based gaze data quality. QualitEye employs a new semantic representation of eye images that contains the information required for verification while excluding irrelevant information for better domain adaptation. QualitEye covers a public setting where parties can freely exchange data and a privacy-preserving setting where parties cannot reveal their raw data nor derive gaze features/labels of others with adapted private set intersection protocols. We evaluate QualitEye on the MPIIFaceGaze and GazeCapture datasets and achieve a high verification performance (with a small overhead in runtime for privacy-preserving versions). Hence, QualitEye paves the way for new gaze analysis methods at the intersection of machine learning, human-computer interaction, and cryptography.
@techreport{elfares25_arxiv2,
title = {{QualitEye}: {Public} and {Privacy}-preserving {Gaze} {Data} {Quality} {Verification}},
author = {Elfares, Mayar and Reisert, Pascal and Küsters, Ralf and Bulling, Andreas},
year = {2025},
doi = {10.48550/arXiv.2506.05908},
publisher = {arXiv},
shorttitle = {{QualitEye}},
}
REFLECTing SPERET: Measuring and Promoting Ethics and Privacy Reflexivity in Eye-Tracking Research
Susanne Hindennach, Mayar Elfares, Céline Gressel, Andreas Bulling
arXiv:2511.18965, 2025.
AbstractLinksBibTeXProject
The proliferation of eye tracking in high-stakes domains - such as healthcare, marketing and surveillance - underscores the need for researchers to be ethically aware when employing this technology. Although privacy and ethical guidelines have emerged in recent years, empirical research on how scholars reflect on their own work remains scarce. To address this gap, we present two complementary instruments developed with input from more than 70 researchers: REFLECT, a qualitative questionnaire, and SPERET (Latin for "hope"), a quantitative psychometric scale that measures privacy and ethics reflexivity in eye tracking. Our findings reveal a research community that is concerned about user privacy, cognisant of methodological constraints, such as sample bias, and that possesses a nuanced sense of ethical responsibility evolving with project maturity. Together, these tools and our analyses offer a systematic examination and a hopeful outlook on reflexivity in eye-tracking research, promoting more privacy and ethics-conscious practice.
@techreport{hindennach25_arxiv,
title = {{{REFLECTing SPERET}}: {{Measuring}} and {{Promoting Ethics}} and {{Privacy Reflexivity}} in {{Eye-Tracking Research}}},
author = {Hindennach, Susanne and Elfares, Mayar and Gressel, C{\'e}line and Bulling, Andreas},
year = {2025},
doi = {10.48550/arXiv.2511.18965},
publisher = {arXiv},
shorttitle = {{REFLECTing SPERET}},
}
Gaze3P: Gaze-Based Prediction of User-Perceived Privacy
Mayar Elfares, Pascal Reisert, Ralf Küsters, Andreas Bulling
arXiv:2507.00596, 2025.
AbstractLinksBibTeXProject
Privacy is a highly subjective concept and perceived variably by different individuals. Previous research on quantifying user-perceived privacy has primarily relied on questionnaires. Furthermore, applying user-perceived privacy to optimise the parameters of privacy-preserving techniques (PPT) remains insufficiently explored. To address these limitations, we introduce Gaze3P – the first dataset specifically designed to facilitate systematic investigations into user-perceived privacy. Our dataset comprises gaze data from 100 participants and 1,000 stimuli, encompassing a range of private and safe attributes. With Gaze3P, we train a machine learning model to implicitly and dynamically predict perceived privacy from human eye gaze. Through comprehensive experiments, we show that the resulting models achieve high accuracy. Finally, we illustrate how predicted privacy can be used to optimise the parameters of differentially private mechanisms, thereby enhancing their alignment with user expectations.
@techreport{elfares25_arxiv,
title = {{{Gaze3P}}: {{Gaze-Based Prediction}} of {{User-Perceived Privacy}}},
author = {Elfares, Mayar and Reisert, Pascal and K{\"u}sters, Ralf and Bulling, Andreas},
year = {2025},
doi = {10.48550/arXiv.2507.00596},
shorttitle = {{{Gaze3P}}},
}
AttentionLeak: What Does Human Attention Reveal About Information Visualisation?
Malte Sönnichsen, Mayar Elfares, Yao Wang, Ralf Küsters, Alina Roitberg, Andreas Bulling
Proc. International Conference on Document Analysis and Recognition (ICDAR), pp. 77--95, 2025.
AbstractLinksBibTeXProject
In scenarios where direct access to displayed content, such as secured web pages or confidential documents, is restricted, eye-tracking data can serve as a side channel for information inference. Represented as human attention maps, eye tracking data is widely used in research, for example, to quantify how users explore visual information. In this work, we specifically focus on visual question-answering (VQA) scenarios to demonstrate, for the first time, that a rich amount of information can be leaked solely from human attention maps. Hence, we assume that an adversary only has access to the gaze attention maps and aims to derive a range of attributes about the image (e.g. the chart type), the question (e.g. question type), and the answer (e.g. the accuracy-based complexity). This information leakage could be the first step towards potentially more complex insights about human perception and cognition. Our experiments demonstrate that deriving attributes is feasible, and simultaneously predicting multiple attributes improves the success rate for attributes that are difficult to infer. This paper highlights potential threats, encouraging the community to address these concerns and develop appropriate privacy-preserving solutions.
@inproceedings{sonnichsen25_icdar,
title = {AttentionLeak: What Does Human Attention Reveal About Information Visualisation?},
author = {Sönnichsen, Malte and Elfares, Mayar and Wang, Yao and Küsters, Ralf and Roitberg, Alina and Bulling, Andreas},
year = {2025},
booktitle = {Proc. International Conference on Document Analysis and Recognition (ICDAR)},
pages = {77--95},
doi = {10.1007/978-3-032-04627-7_5},
}
2024
PrivatEyes: Appearance-based Gaze Estimation Using Federated Secure Multi-Party Computation
Mayar Elfares, Pascal Reisert, Zhiming Hu, Wenwu Tang, Ralf Küsters, Andreas Bulling
Proc. ACM on Human-Computer Interaction (PACM HCI), 8 (ETRA), pp. 1--23, 2024.
AbstractLinksBibTeXProject
Latest gaze estimation methods require large-scale training data but their collection and exchange pose significant privacy risks. We propose PrivatEyes - the first privacy-enhancing training approach for appearance-based gaze estimation based on federated learning (FL) and secure multi-party computation (MPC). PrivatEyes enables training gaze estimators on multiple local datasets across different users and server-based secure aggregation of the individual estimators' updates. PrivatEyes guarantees that individual gaze data remains private even if a majority of the aggregating servers is malicious. We also introduce a new data leakage attack DualView that shows that PrivatEyes limits the leakage of private training data more effectively than previous approaches. Evaluations on the MPIIGaze, MPIIFaceGaze, GazeCapture, and NVGaze datasets further show that the improved privacy does not lead to a lower gaze estimation accuracy or substantially higher computational costs - both of which are on par with its non-secure counterparts.
@article{elfares24_etra,
title = {PrivatEyes: Appearance-based Gaze Estimation Using Federated Secure Multi-Party Computation},
author = {Mayar Elfares and Pascal Reisert and Zhiming Hu and Wenwu Tang and Ralf Küsters and Andreas Bulling},
year = {2024},
journal = {Proc. ACM on Human-Computer Interaction (PACM HCI)},
volume = {8},
number = {ETRA},
pages = {1--23},
doi = {10.1145/3655606},
}
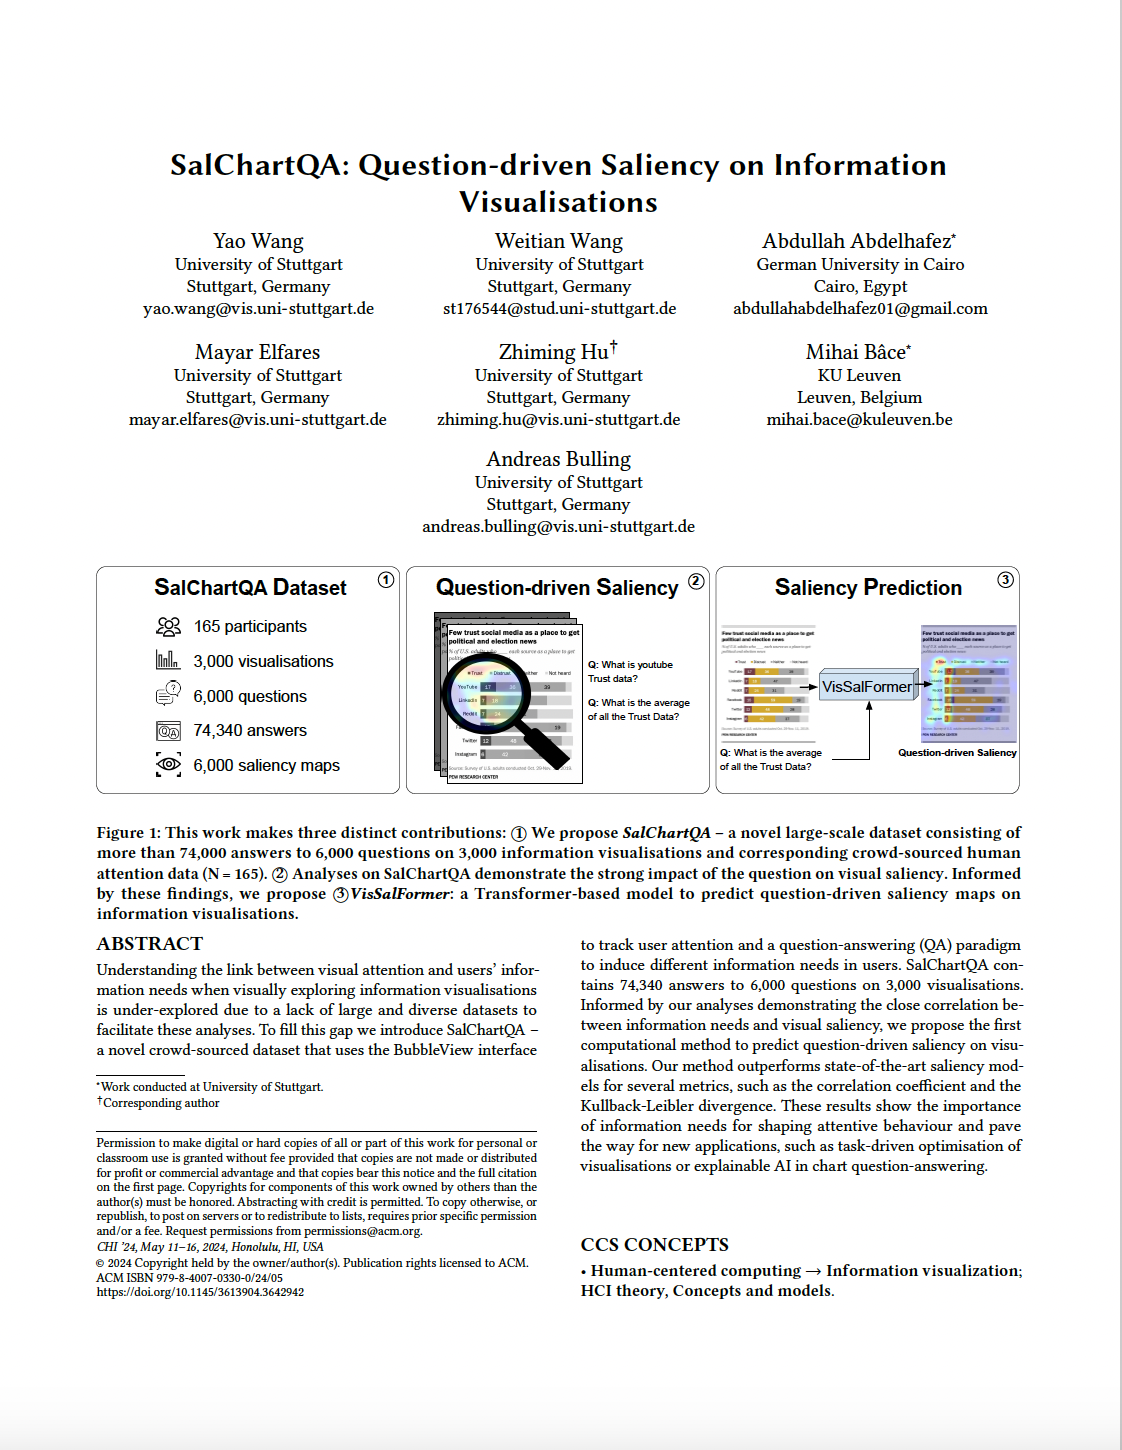
SalChartQA: Question-driven Saliency on Information Visualisations
Yao Wang, Weitian Wang, Abdullah Abdelhafez, Mayar Elfares, Zhiming Hu, Mihai Bâce, Andreas Bulling
Proc. ACM SIGCHI Conference on Human Factors in Computing Systems (CHI), pp. 1--14, 2024.
AbstractLinksBibTeXProject
Understanding the link between visual attention and user's needs when visually exploring information visualisations is under-explored due to a lack of large and diverse datasets to facilitate these analyses. To fill this gap, we introduce SalChartQA – a novel crowd-sourced dataset that uses the BubbleView interface as a proxy for human gaze and a question-answering (QA) paradigm to induce different information needs in users. SalChartQA contains 74,340 answers to 6,000 questions on 3,000 visualisations. Informed by our analyses demonstrating the tight correlation between the question and visual saliency, we propose the first computational method to predict question-driven saliency on information visualisations. Our method outperforms state-of-the-art saliency models, improving several metrics, such as the correlation coefficient and the Kullback-Leibler divergence. These results show the importance of information needs for shaping attention behaviour and paving the way for new applications, such as task-driven optimisation of visualisations or explainable AI in chart question-answering.
@inproceedings{wang24_chi,
title = {SalChartQA: Question-driven Saliency on Information Visualisations},
author = {Yao Wang and Weitian Wang and Abdullah Abdelhafez and Mayar Elfares and Zhiming Hu and Mihai B{\^a}ce and Andreas Bulling},
year = {2024},
booktitle = {Proc. ACM SIGCHI Conference on Human Factors in Computing Systems (CHI)},
pages = {1--14},
doi = {10.1145/3613904.3642942},
}
2023

Federated Learning for Appearance-based Gaze Estimation in the Wild
Mayar Elfares, Zhiming Hu, Pascal Reisert, Andreas Bulling, Ralf Küsters
Proceedings of The 1st Gaze Meets ML workshop, PMLR, pp. 20--36, 2023.
AbstractLinksBibTeXProject
Gaze estimation methods have significantly matured in recent years, but the large number of eye images required to train deep learning models poses significant privacy risks. In addition, the heterogeneous data distribution across different users can significantly hinder the training process. In this work, we propose the first federated learning approach for gaze estimation to preserve the privacy of gaze data. We further employ pseudo-gradient optimisation to adapt our federated learning approach to the divergent model updates to address the heterogeneous nature of in-the-wild gaze data in collaborative setups. We evaluate our approach on a real-world dataset (MPIIGaze) and show that our work enhances the privacy guarantees of conventional appearance-based gaze estimation methods, handles the convergence issues of gaze estimators, and significantly outperforms vanilla federated learning by 15.8% (from a mean error of 10.63 degrees to 8.95 degrees). As such, our work paves the way to develop privacy-aware collaborative learning setups for gaze estimation while maintaining the model’s performance.
@inproceedings{elfares23_gmml,
title = {Federated Learning for Appearance-based Gaze Estimation in the Wild},
author = {Elfares, Mayar and Hu, Zhiming and Reisert, Pascal and Bulling, Andreas and K{\"u}sters, Ralf},
editor = {Lourentzou, Ismini and Wu, Joy and Kashyap, Satyananda and Karargyris, Alexandros and Celi, Leo Anthony and Kawas, Ban and Talathi, Sachin},
year = {2023},
booktitle = {Proceedings of The 1st Gaze Meets ML workshop, PMLR},
volume = {210},
pages = {20--36},
url = {https://proceedings.mlr.press/v210/elfares23a.html},
publisher = {PMLR},
series = {Proceedings of Machine Learning Research},
}
2021
Multi-limb Split Learning for Tumor Classification on Vertically Distributed Data
Omar Ads, Mayar Elfares, Mohammed Salem
Proceedings of the Tenth International Conference on Intelligent Computing and Information Systems (ICICIS), pp. 88-92, 2021.
AbstractBibTeXProject
Brain tumors are one of the life-threatening forms of cancer. Previous studies have classified brain tumors using deep neural networks. In this paper, we perform the later task using a collaborative deep learning technique, more specifically split learning. Split learning allows collaborative learning via neural networks splitting into two (or more) parts, a client-side network and a server-side network. The client-side is trained to a specific layer named as the cut layer. Then, the rest of the training is resumed on the server-side network. Vertical distribution, a method for distributing data among organizations, was implemented where several hospitals hold different attributes of information for the same set of patients. To the best of our knowledge, this paper is the first paper to implement both split learning and vertical distribution for brain tumor classification. Using both techniques, we were able to achieve train and test accuracy greater than 90% and 70%, respectively.
@inproceedings{ads21_icicis,
title = {Multi-limb Split Learning for Tumor Classification on Vertically Distributed Data},
author = {Omar Ads and Mayar Elfares and Mohammed Salem},
year = {2021},
booktitle = {Proceedings of the Tenth International Conference on Intelligent Computing and Information Systems (ICICIS)},
pages = {88-92},
}


